Showing posts with label Data loading. Show all posts

Friday, May 24, 2024

When was the last data load?

I had a request recently for a simple way for users to know when the last data load occurred. They could go into process details or jobs, maybe, but was there a simple way to check from within a report, data grid, or even Smart View. There may be something better, but here's what I did.

I created an account called LL_DateTime. I originally was going to put the year in one account, month in another, etc. but I ended just using the one account.

Within data management (this part isn't in the new interface yet) I created a logic group to duplicate a record. I picked a retained earnings account for one of the primary legal entities so there would always be a data point to duplicate.


After assigning the logic group to the location, I used a SQL map to change the amount. The two SQL functions in use here are SUBSTR (get a subset of a string) and SYSTIMESTAMP (date and time on the server).

The SYSTIMESTAMP returns a format of 28-MAY-24 02.34.56.654321 PM -00:00  which isn't something we would be able to load as an amount. So SUBSTR is used to pull out pieces of this and to combine them into something useful. There are a few components that need mapping. The month of May needs to be converted to a number. The AM/PM indicator needs to be converted to a 24 hour clock (again, trying to load the date and time as one amount. There are a couple of different WHENs in use to direct the calc (if May, then 05; if PM, then add .12 [12 hours]). Admittedly there is probably a more elegant way of converting the month to a number without having to enumerate all of the options.

So, the format of the output looks like this: 20240528.1434. This is an easy number to load and report.

The last part of the output (00:00) indicates the timezone. In this case, it is UTC. This could be converted to a specific timezone but in the case of worldwide users, most people would have to convert anyway. It's better to just use UTC and let each user deal with summer time, etc.

The last part of the puzzle here was to create a simple data grid with all of the point of view members locked except for the year and period. This way users can check and see when the data was last loaded. They can also replicate the point of view and use Smart View, etc.




Friday, April 19, 2024

EPM Cloud Data Integration - Dealing with [Parent].[Child]

Another day, another solution to remember for later.

When moving data from one application to another, shared members can sometimes flow through the integration with [Parent].[Child] notation. If loading the child member to the target application and the target does not have the same hierarchy, then this won't work. Or, like I did today, when loading entity elimination data from FCC to Planning, then only the parent entity is needed.


A #FORMAT map can do some of this (and maybe all). #FORMAT can ignore specific positions, replace text, etc. Here's the doc link. But there are limitations to #FORMAT and the need for SQL scripting comes into play.

https://docs.oracle.com/en/cloud/saas/enterprise-performance-management-common/erpia/format_mask_mapping_for_target_values.html 

With SQL scripting, here's what to do. There are two main SQL functions to use: SUBSTR and REGEXP_INSTR. SUBSTR returns a subset of a string. REGEXP_INSTR searches for a character and can return different things, mainly the position of the character.

In the particular use case shown here, only the Parent portion was needed, so omit the first [ and then omit everything after the first ]. Here's the SQL using the two functions. With SUBSTR, we start with the string in the field ENTITY, start with position 2, and then use REGEXP_INSTR to know how far to go. This function is searching for the first ] and returning its position within the string. That result is the last parameter for the SUBSTR function (how far to go) but we need to subtract 2 from the result. Subtracting 1 since the first character is being omitted and subtracting another 1 as the ]  - the character being searched - isn't needed.

SUBSTR(ENTITY,2,REGEXP_INSTR(ENTITY,'[]]+', 1,1,0)-2)

Since I'm using a wildcard map to process all incoming records, I also wanted to flag members that come through without the [parent].[child] format, so I used SUBSTR again to check the first character. If [ then use the above; otherwise, flag that there is a new entity without [parent].[child] (which would mean the member is not shared) and should be dealt with differently, which could be an explicit map, passthrough, etc.

The ending result looks like this (I also added a prefix to the parent so the result looks like ELIM_parent). The lines starting with -- are comments.


This use case is focusing on isolating the parent. If just the child is needed, change the parameters for SUBSTR and REGEXP_INSTR, respectively, to focus on the end of the record without the last ] on the end and search for the position of the second [ in the string.


Wednesday, January 17, 2024

Data Exchange - DRCRSplit for Delimited Files

Recently had to solve a problem during an implementation and as I've done before, I'm adding the solution here so I can find it again.

An incoming trial balance file is delimited and has two columns for the amount: a debit column and a credit column. Each record will have a value in one of these but not both. If the file was fixed format instead of delimited, there is a built-in import format expression called DRCRSplit that will deal with the two columns. With the function, you specify the midpoint of the overall character count but with delimited files you don't have a consistent midpoint character count, so it doesn't work with delimited files.

Like maybe some of you reading this, I did a Google search on this topic and found multiple Oracle forum posts, CloudCustomerConnect posts, etc. asking the same question over several years but didn't find an easy solution. There was a posted answer that combined the DRCRSplit function with the Column function, but as pointed out by someone else that solution causes data problems. So, below is what I did. There may be a more elegant way of solving this problem, but the solution worked for me.

I mapped the debit and credit balance columns to separate attribute fields and for the regular amount field, I mapped the account field to it. Each record needs a numeric amount; otherwise, it will get dropped on the import. I'm thinking the year could be used as the placeholder amount if it were available on each record. I'm guessing that one of the amount fields would probably work in conjunction with the no zero suppress expression.

[Editor note: if the right sidebar is covering part of the picture, click it to see the full detail]


Next, I used a SQL map on the entity to (a) pass the entity through and (b) to populate the amount. Below, the entity portion isn't shown. The AMOUNTX field (the target amount) is populated from the debit column if it is not equal to zero and from the credit column if the debit is equal to zero. Anything placed in an attribute field is stored as a string, so the TO_NUMBER function converts the string back to a number. If there was a need to deal with quotes, spaces, commas, etc. in the number as thousands separators or decimals, that could be addressed with either a format on TO_NUMBER or using one of the REGEXP functions.


I attached this SQL to the entity dimension mapping. If the entity dimension needs more mapping and the SQL gets in the way of using the other mapping types (explicits, etc.) then attach the SQL to another dimension, like Data Source. Any of them will work, so the SQL should be placed somewhere inconspicuous.


Thursday, September 7, 2023

FCC - Doing Away with Separate Loads for Balance Sheet and Income Statement

THIRD UPDATE - Feb 2025

In the 25.02 release this functionality was updated and should work. Please check the release notes and the doc for instructions.


TWO UPDATES - Sep 2023

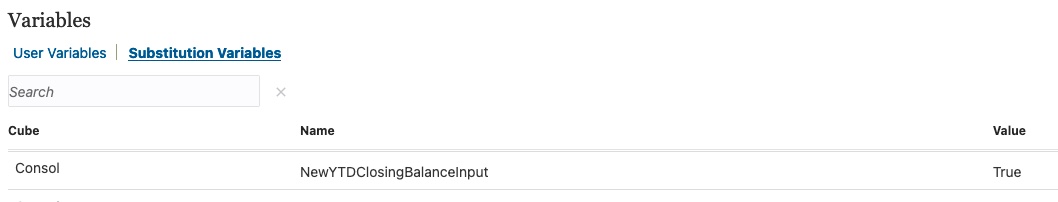
First, I have to apologize - I got the name of the variable wrong. It should be: NewLoadYTDClosingBalanceInput

Second, Oracle product management posted on Cloud Customer Connect yesterday that the feature isn't working correctly for profit and loss accounts and it will be addressed. No indication on timeline.


It's been a while since the last blog post so thought I'd do one on a new feature that's everyone has been wanting to see: loading BS and PL data together instead of separately. The funny (well, not funny) thing is that I missed the announcement - it was listed down in the Actions and Considerations section of the release notes instead of in the regular new features section. A friend pointed it out to me and I'm thankful they did.

The August release (23.08) introduced a change where you don't have to do separate loads for the balance sheet and the income statement in order for the system to reverse out the prior period closing balance. More specifically, the system would reverse the prior period's periodic closing balance and carried over the income statement from the prior year in the first period. Now, the system reverses the YTD closing balance from the prior period and does nothing for the income statement accounts in the first period.

I tried this out for myself and got the process to work. There are a couple details that aren't obvious in the current documentation, so I'm sharing them here. One is the next line and one is at the bottom.

First, there is a substitution variable that is required to enable the process: NewYTDClosingBalanceInput.


Next, set up the metadata so that income statement accounts have the FCCS_Mvmts_NetIncome member assigned as the default movement. The balance sheet accounts should already have the assignment. Note: it is recommended to keep FCCS_Mvmts_NetIncome as a level 0 member and not make it a parent. I thought about making it a parent with the non cash income statement movements as children as well as a regular income statement movement and was advised against it.


Next, in Data Exchange, populate the movement dimension for both balance sheet and income statement accounts with FCCS_ClosingBalance_Input. Here, I'm using a SQL statement to map multiple dimensions at once as it's faster than mapping dimensions separately, but either way works. Note: your movement dimension may not be UD7, so use the appropriate field. And yes, this is the new Data Exchange interface to which we should all be transitioning.


Now, when data is loaded and consolidated, the movement and reversals are properly calculated - top two rows have an asset and the bottom two rows have an expense.


I need to do further testing and verification but so far so good. 

The other not so obvious detail is that the movement member must be somewhere under FCCS_Mvmts_SubTotal. So if you also have statistical data to load, which normally goes to FCCS_No Movement, that will seemingly need to be a separate load.

I've already changed the design for two projects to use this feature. The time for the design change and the extra setup should easily be recouped in the quicker loads (one vs two).